Recover a Drupal website by checking its database, uploaded files, software and configuration as related sources. A surviving folder of images or a public archive can help, but neither proves that the original entities, field values and relationships are intact. Start by identifying the Drupal version and the sources that belong to that installation.
When native recovery is unavailable, public content can inform a reconstruction. The key is to document what the new records represent and which historical relationships remain unknown rather than treating rendered pages as a complete original data model.
Preserve the native sources before examining archive alternatives
The Drupal User Guide’s backup section identifies database data, site settings, uploaded files and customized software as parts of a complete backup. It also recommends testing a development copy. Determine what actually survives before deciding that a public-content rebuild is necessary.
Record the version, source date and scope of each copy. A configuration export, database dump, uploaded-file directory and code repository serve different roles. Ask the hosting provider or authorized developer for missing related material, without altering the remaining originals.
Use a qualified review of an isolated working copy. Do not import a mismatched database or overwrite a current site merely to test whether an old backup opens. Compatibility and source consistency need assessment first.
Identify records, fields and relationships separately
For modern Drupal (version 8 and later), the Entity API reference distinguishes content entities from configuration entities and describes content stored in fields. That distinction is useful in recovery: a visible article can reveal some content, while the settings controlling its display and the other records it references may need separate sources.
For an archive-led rebuild, ask which information is an independent record and which is merely a displayed label. A named author might identify a public byline without revealing a private user account. A linked topic might indicate a taxonomy relationship without proving its original identifier or every membership.
Do not recreate private accounts, permissions or unpublished records from guesses. Public evidence can support a new approved structure, but the difference between reconstruction and restoration of original data must remain clear.
Draft a small entity-gap specification
Before a large migration, prepare a specification for one representative content type. This is a planning exercise, not a demonstrated Drupal recovery.
- Record identity: historical public URL, title and supporting source date.
- Visible fields: copy, image, document, date or other value that is actually supported.
- Relationships: linked author, topic, media or related record, with the evidence for the association.
- Unknowns: missing field values, translations, revisions, private data or display configuration.
- New decisions: approved content type, required fields, replacement media and handling of absent optional values.
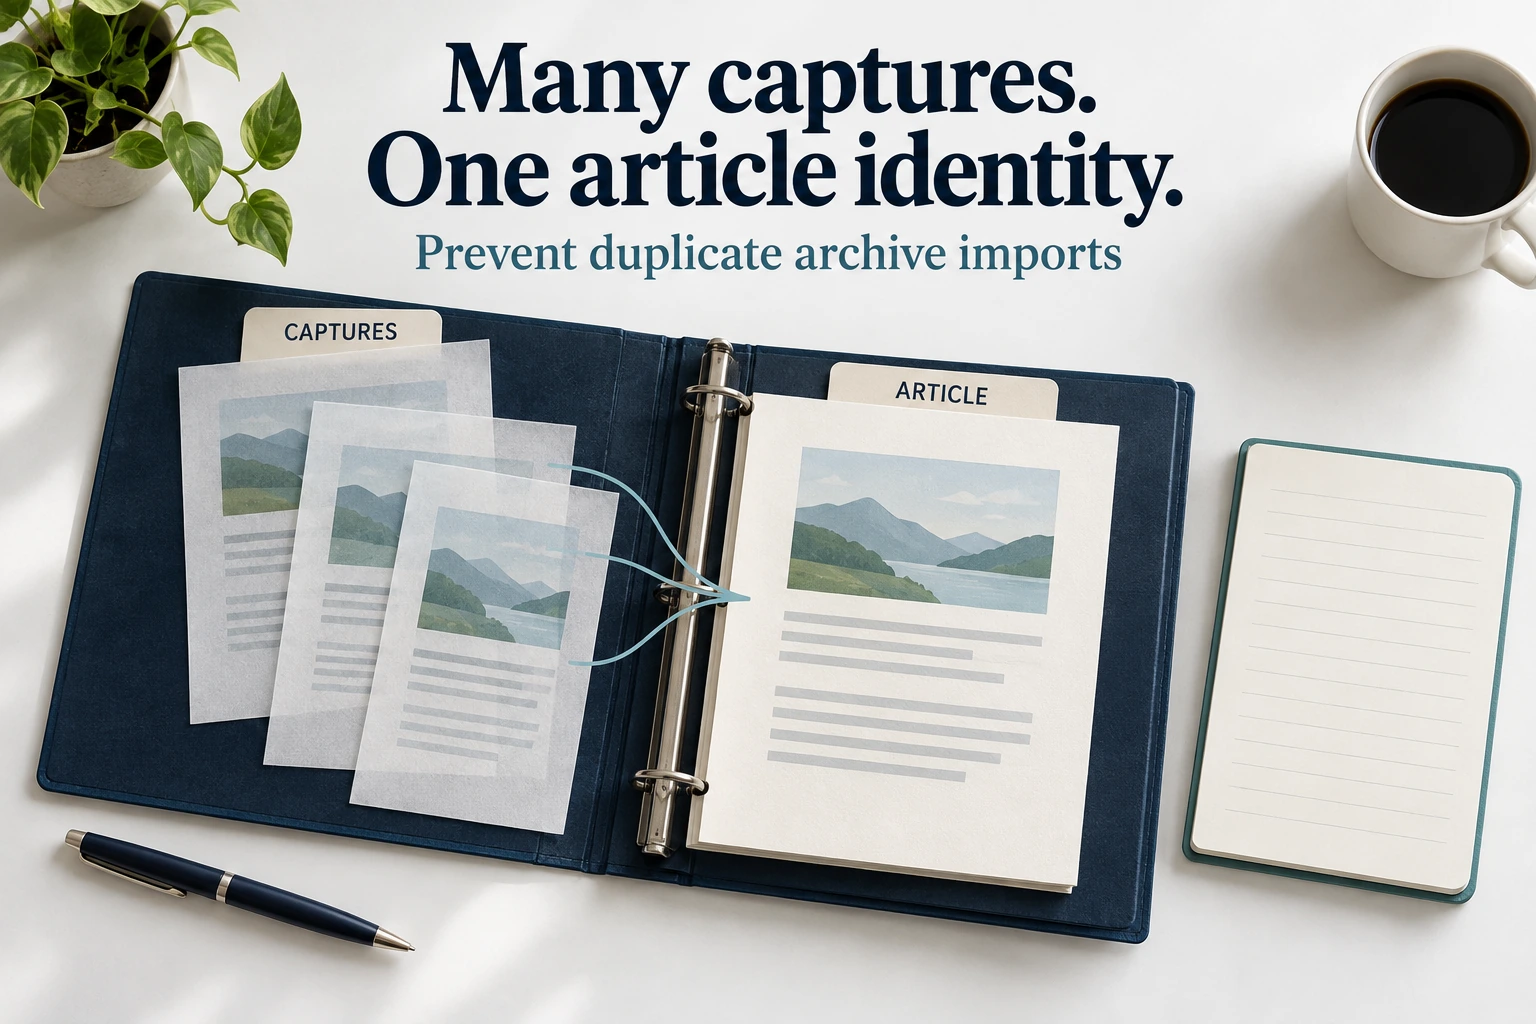
Do not treat every captured path as an independent record. A category listing, a filtered result and several captures of the same article can be different representations of related content. Establish identity before importing them.
A useful acceptance test is whether editing an approved field changes the intended page and whether its related links remain correct. A screenshot alone cannot establish those relationships.
Match files to their intended uses
Inspect surviving images and documents separately from their database references. A file may be usable while the original association is missing. Conversely, a retained record can refer to an absent file.
Map each required file to its documented page or field using original data where available and visible evidence otherwise. Keep a provenance note and avoid creating associations solely from similar filenames. Record which links and captions were reconstructed.
Do not regard thumbnails as equivalent to full-size sources or republish files without checking permission and suitability. Missing documents containing substantive information should be referred to the owner; decorative substitutes cannot replace their facts.
Protect public routes while recreating the internal model
Keep an inventory of the exact historical page paths that matter to visitors and existing links. A newly chosen record structure or new identifier should not silently change those paths.
Document each delivered destination and test it directly, without starting from an administrator preview. Where preserving a route is not feasible, obtain approval for the separately reviewed alternative rather than assuming a blanket homepage redirect solves the problem.
Check listings as well as single records. A reconstructed article can be correct while its topic listing, pagination or related-content link remains wrong. Include those relationships in the acceptance specification.
Approve a limited pilot before a wider reconstruction
Use a representative content record, its media and its relevant listing to evaluate the proposed structure. Verify source fidelity, field updates, display on small screens, public paths and missing-value handling. Any temporary test content should be identified and removed before handover.
Then reconcile the delivered records against the agreed inventory. Record original data restored, public evidence reconstructed, approved new configuration and unresolved gaps separately. Do not imply that recreated current records include every historical revision or translation.
The archive restoration guide covers the broader source-to-delivery process. A Drupal project still needs version-specific technical review; this article does not claim an executed import or guarantee recovery of every entity or extension.
Drupal source questions
Can public pages reveal all original field values?
No. They establish displayed material. Hidden, unpublished or private values require other authorized sources.
Do surviving files prove that their Drupal associations survive?
No. Check both the files and the records that refer to them. When associations must be recreated, document the supporting evidence.
Should an archive replace a usable native backup?
Not by default. Preserve and evaluate the native sources first. Archives can help fill supported public-content gaps where necessary.